
Does your provider break your tool calls?
NoBadActions
Tool calls that parse the first time.
Tool calls that parse, JSON that fits the schema.
Tool calls that parse, JSON that fits the schema.



Same weights. Different reliability.
Reliability comes from how a model is served. The same open weights, on different providers, break anywhere from 0.1% to 10% of tool calls. Across 46 models on OpenRouter, the worst provider typically fails 30 times as often as the best.
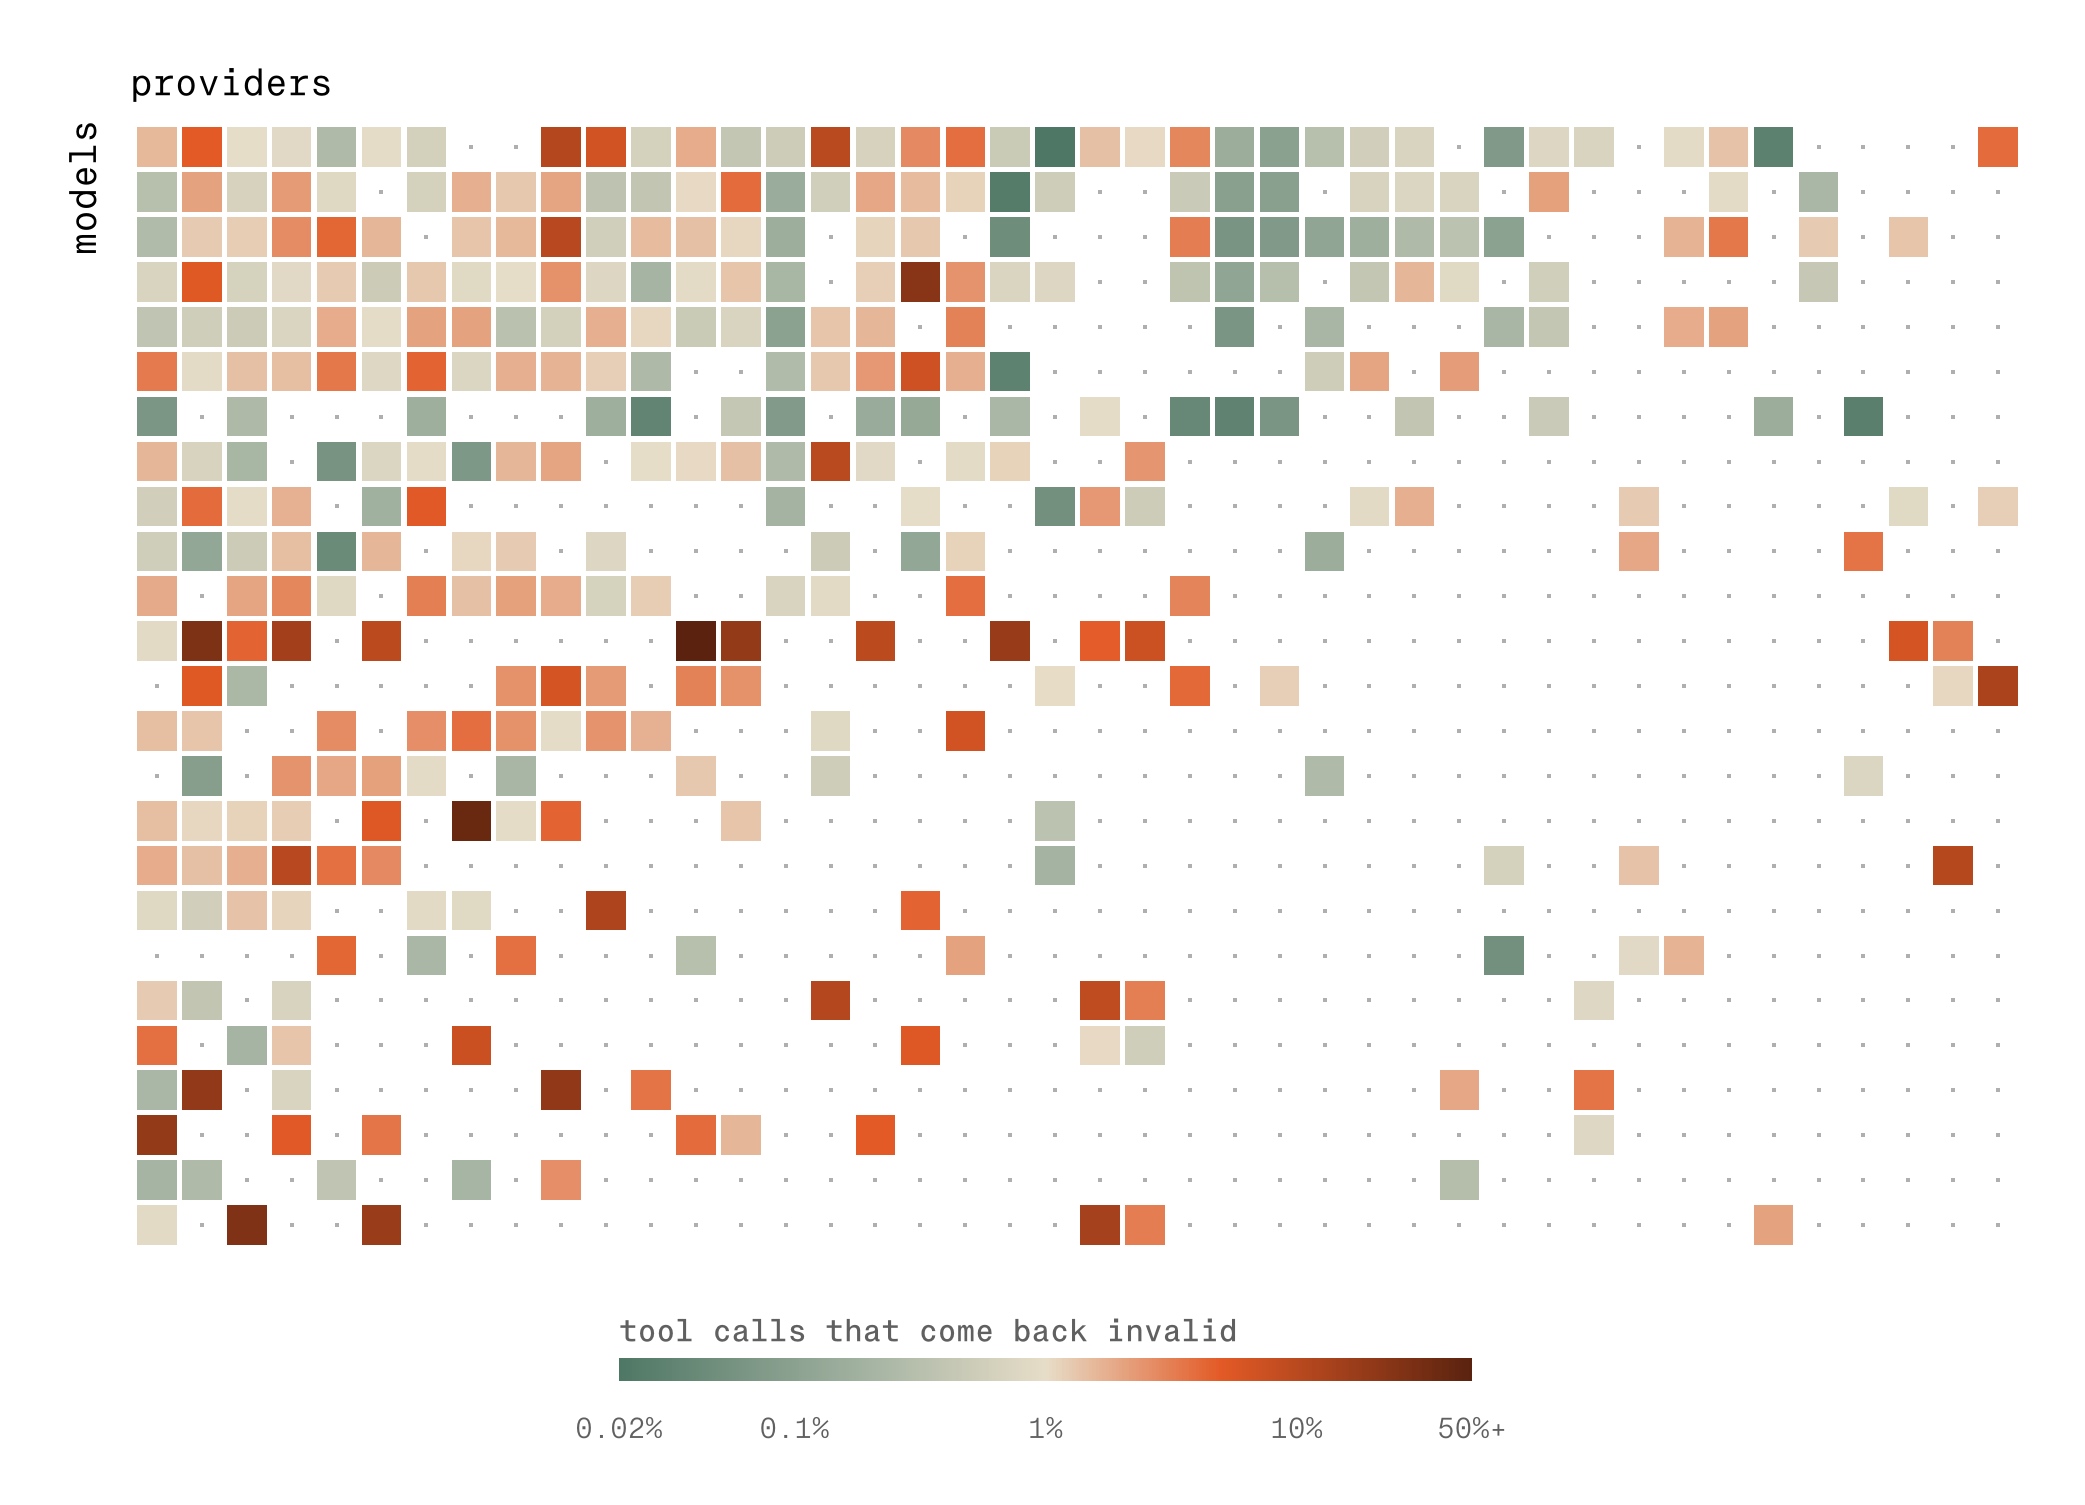
OpenRouter's published tool-call error rates, October 27 to November 2, 2026. The chart shows the 25 models with the most providers and the 42 providers serving at least three of them: 368 provider-model pairs with 1,000 or more tool calls a day.
Valid tool calls and JSON, as the model writes them.
.txt builds structured generation into the inference engine. At every step, the model can only write what your tools and schemas allow. We work with inference providers, model makers and teams that ship models on devices.
- Inference providers
Make your endpoint the one agents can trust.
Runs inside vLLM, SGLang and TensorRT-LLM, in your cluster. No slowdown. Pilot on one model. Serve it in weeks.
- Model makers
Judged on the model you trained, not on how it's served.
Before release, get a report on where your model breaks its own format, and how often. We run paired benchmarks with and without .lambda, for you to publish. Your result becomes the reference.
- On-device AI
No broken tool calls. Even on small models.
Qwen3-0.6B goes from 46.9% to 55.1% on BFCL, with no repair retries. Runs on your hardware and inside your runtime, offline.